Aindrak combines high-speed native C++ systems with classical Pāṇinian graph algorithms and neural reasoning models. Each layer is engineered for zero-hallucination accuracy, low compute footprint, and real-time responsiveness.
How the Aindrak subprojects interact: from on-device phonetics to formal Pāṇinian compilers and sovereign inference runtimes.
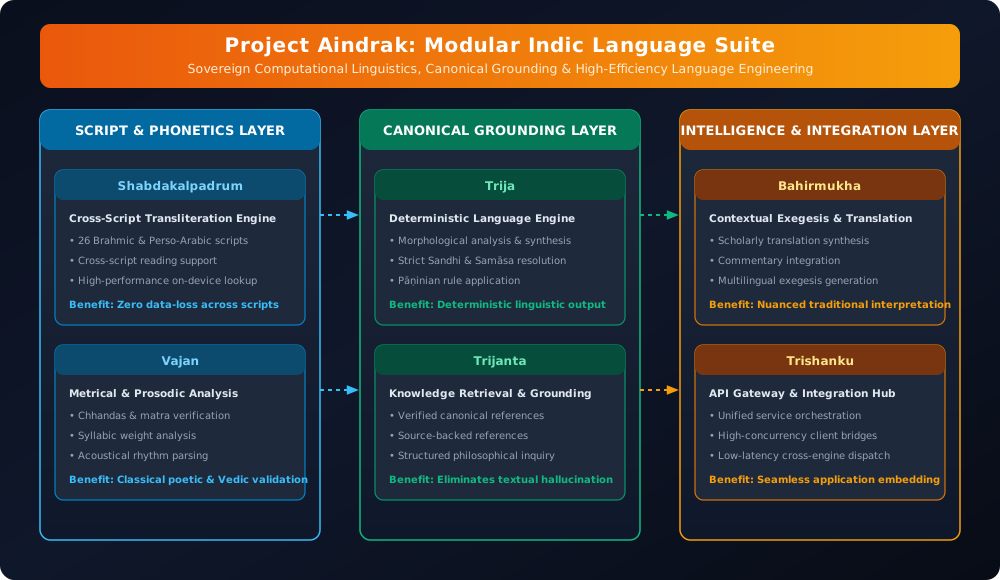
Each component is designed with clear interface boundaries, allowing standalone deployment on edge devices or combined orchestration in enterprise environments.
A native C++ transliteration and phonetic normalization engine designed for instant, zero-latency execution directly on mobile devices and embedded hardware. Supporting 26 Indian languages and Brahmic scripts, it enables users to seamlessly speak in one tongue and read in another script with zero cloud calls.

A high-efficiency grammatical reasoning engine built on Pāṇini’s Aṣṭādhyāyī and classical grammatical principles. Trija provides deterministic morphological compilation, resolving inflections, roots (dhātus), and prefixes (upasargas) with mathematical precision.

Helps users find verified, source-backed information from classical Sanskrit and Indian literature. Standard generative models frequently hallucinate or distort classical texts; Trijanta replaces probabilistic guesses with verified references anchored directly in authentic canonical works.
A high-performance API gateway and service integration hub. Trishanku provides unified access to authenticated Indic linguistic knowledge and models, allowing developer applications to integrate sovereign linguistic capabilities via standard REST and streaming APIs.
An embedded inference library and CLI tool built for low-latency text evaluation. Bahirmukha provides in-process scholastic translation and commentary generation capabilities directly linked into Trishanku.
The dataset and training companion for Bahirmukha and Trishanku. Bahiranana automates supervised dataset compilation, grammatical benchmark generation, and training pipeline orchestration.
Specialized research and training toolsets for sovereign Indic foundation models. Antarmukha and Antaranan facilitate advanced experimentation with structure-aware token architectures, dataset grounding, and high-efficiency model training.
Western AI benchmarks (e.g. MMLU, GSM8K) fail to evaluate grammatical correctness, inflectional integrity, and semantic preservation in Indian languages. Vajan provides standardized, rigorous benchmarks for Sanskrit and Indic language models.